 BlackArc
TL;DR
Retrieval-Augmented Generation (RAG) bolts a search engine onto an LLM so it stops hallucinating facts. But naive RAG retrieves on every query — even ones the model already knows — which is slow, expensive, and pollutes the prompt with noisy documents that can make answers worse. DeepRAG fixes this by making retrieval a decision the model learns to make. It decomposes a question into a chain of sub-queries, and at each sub-query it makes a binary “atomic decision”: retrieve external docs, or answer from my own parametric knowledge. The model is trained in two stages — first imitating cheap-but-correct trajectories found via binary tree search, then calibrating its retrieve/don’t-retrieve instinct with preference pairs (DPO-style). The result: across six QA benchmarks it beats adaptive-RAG and reasoning-RAG baselines by ~21.99% accuracy (headline figure 26.4%) while cutting the number of retrievals. The deeper win is calibration — the model’s retrieval choices become genuinely correlated with what it does and doesn’t know.
Problem & Motivation
The pain, stated in one sentence: RAG systems retrieve blindly, and blind retrieval is both wasteful and actively harmful.
Unpack that. There are two failure modes the paper attacks:
-
Bad decomposition. Complex questions (“total runtime of all Lord of the Rings movies?”) need multiple steps: first find the three titles, then each runtime, then sum. Single-shot RAG retrieves once against the original question and gets a messy soup of documents. Iterative RAG retrieves multiple times but LLMs are bad at generating precise, atomic sub-queries on the fly, so the retrieval targets are vague.
-
Retrieving when you shouldn’t. “What are the three Lord of the Rings movies?” — the model already knows this cold. Forcing a retrieval here wastes a call and, worse, injects passages that may distract or mislead the model. The paper is blunt: unnecessary retrieval “can be redundant and may introduce noise, and degrade the quality of generated responses.” Conversely, the final summation step (“178+179+201”) needs no retrieval at all — it’s pure reasoning over already-gathered facts.
Prior “adaptive RAG” approaches tried to decide when to retrieve, but each is brittle:
- Classifier-based — train a separate linear head to predict “retrieve y/n.” Needs extra parameters and labeled data.
- Confidence-based — retrieve when token-level uncertainty crosses a threshold. Threshold-tuning is fragile and uncertainty is a poor proxy for “do I actually know this.”
- LLM-based (Self-RAG, etc.) — just ask the model “should I retrieve?” But models are notoriously bad at knowing their own knowledge boundaries, so they answer unreliably.
DeepRAG’s bet: the model can learn to recognize its own knowledge boundary, if you train it with the right signal — trajectories that are both correct and minimally retrieval-hungry.
What’s New (Core Contribution)
Three genuine contributions, each a “before → now”:
-
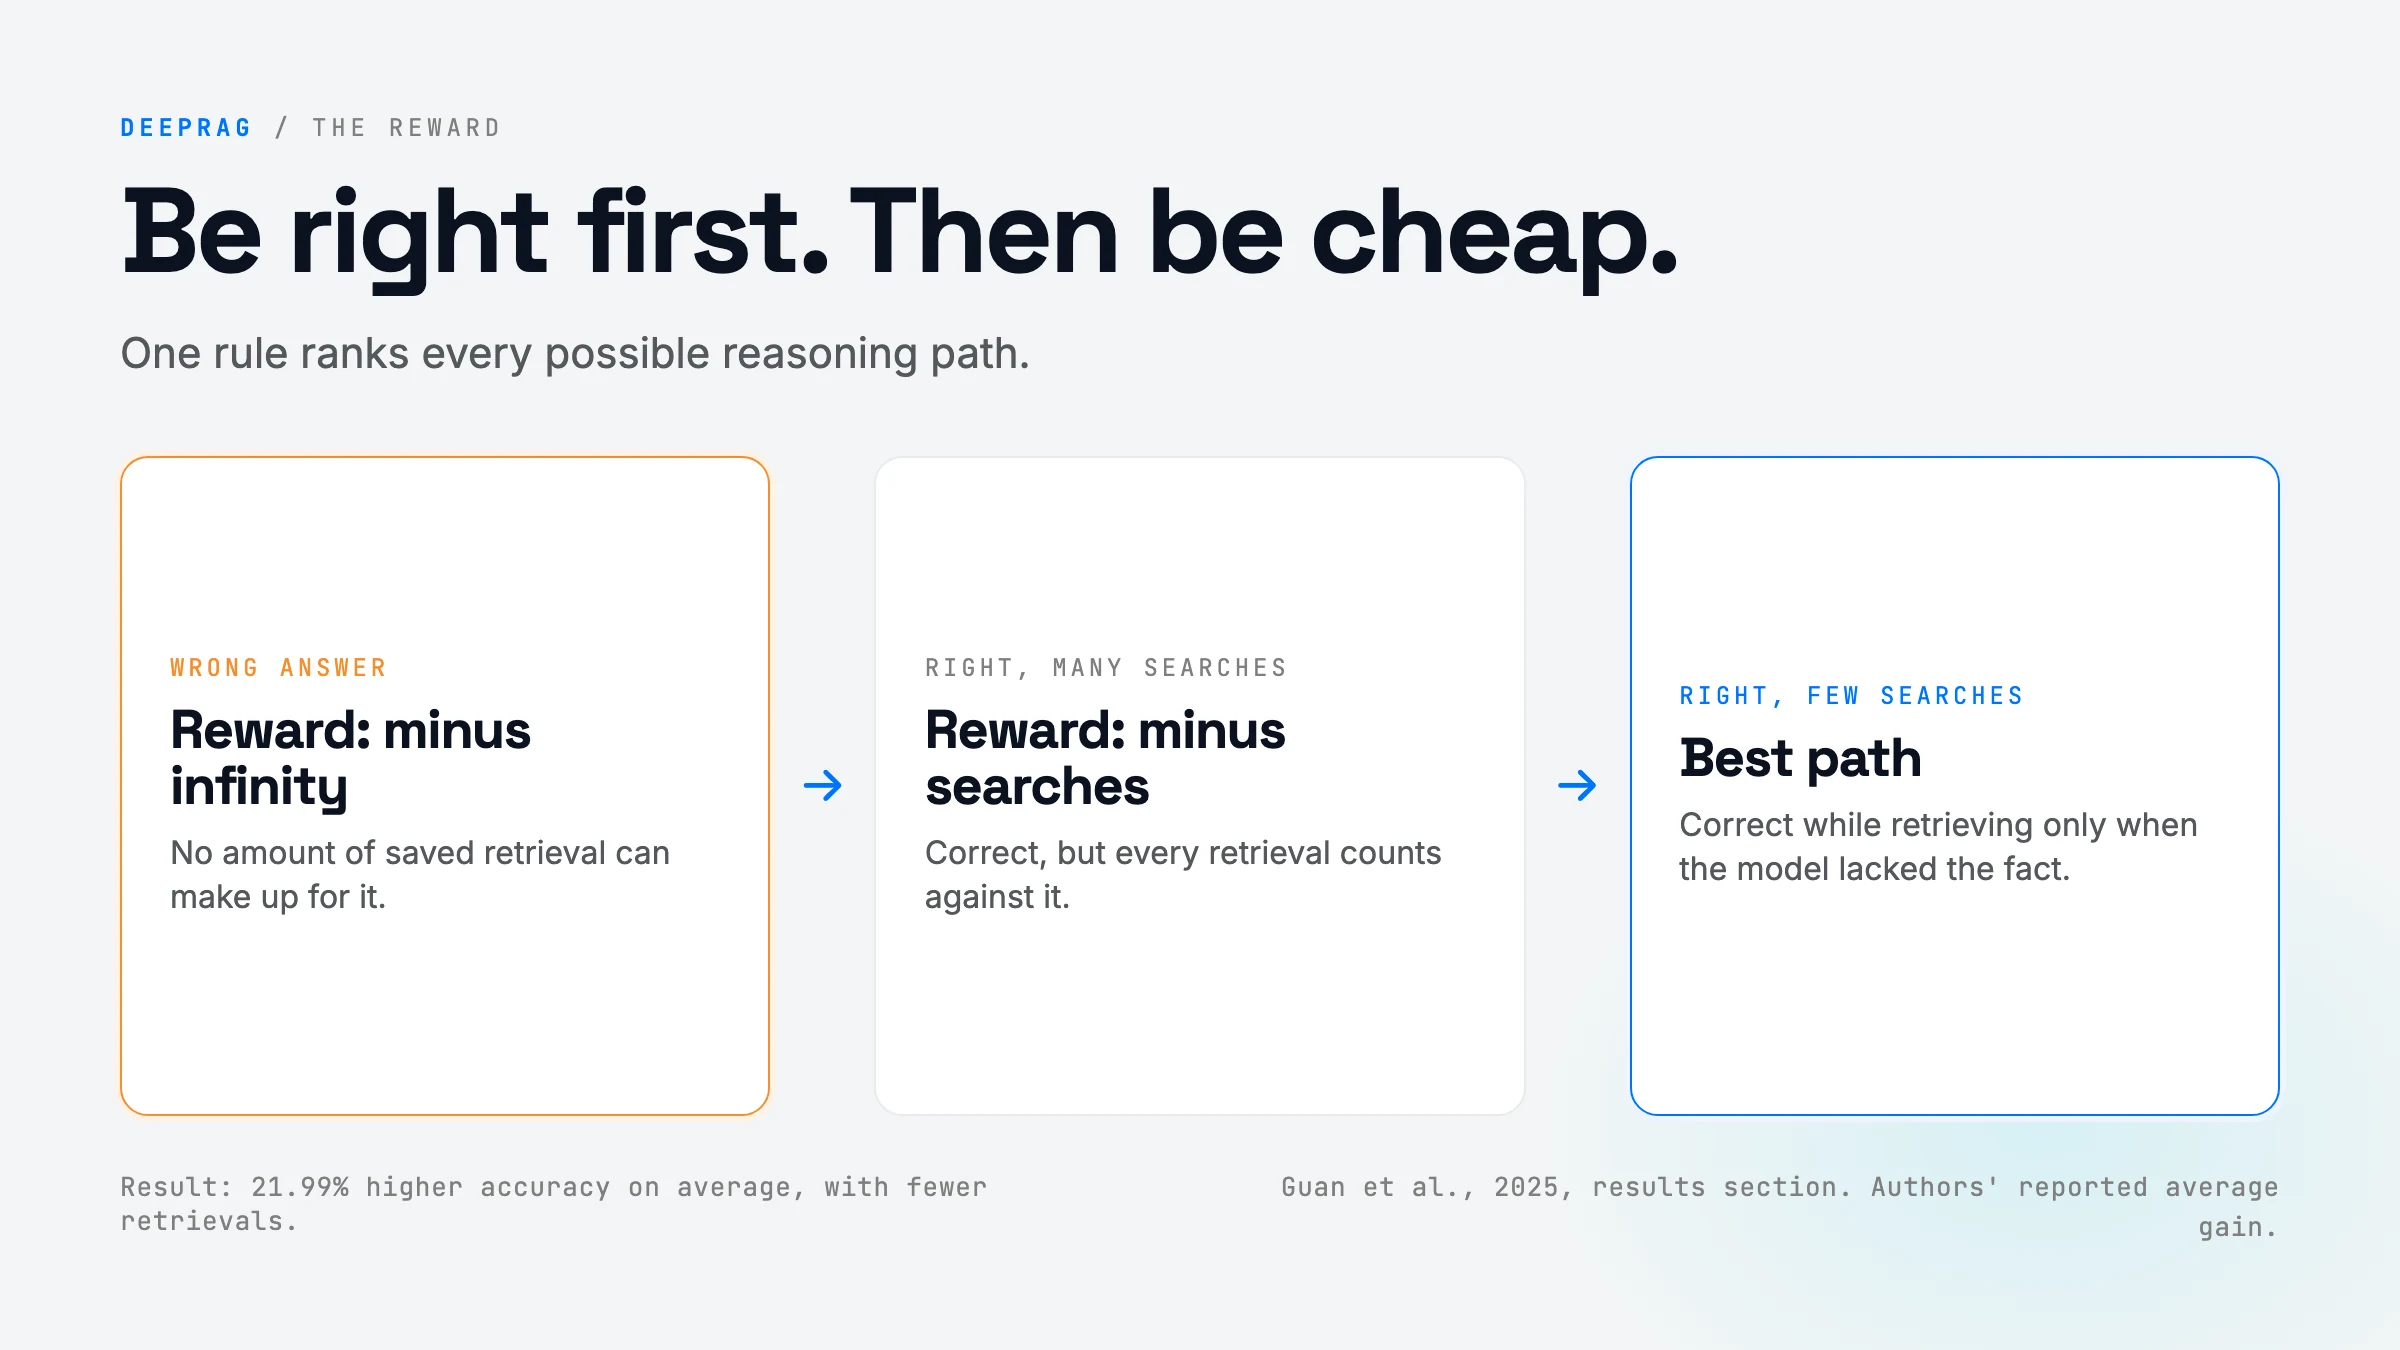
MDP formulation of retrieval-augmented reasoning. Before: RAG was a fixed pipeline (retrieve → read → generate) or an ad-hoc loop. Now: it’s a Markov Decision Process with states (partial solution), actions (terminate? retrieve?), transitions, and a reward that explicitly trades off correctness against retrieval cost. This reframing is what licenses everything else — once it’s an MDP you can search it and optimize a policy over it.
-
Binary Tree Search for data synthesis (not inference). Before: tree-search RAG (e.g. AirRAG, MCTS methods) runs an expensive search at inference time, paying that cost on every user query. Now: DeepRAG runs the tree search offline, once, to manufacture training data — the cheapest correct trajectories — then bakes the behavior into the model’s weights. Inference is a plain greedy decode. This is the key efficiency move and easy to miss.
-
Chain of Calibration (preference training on the atomic decision). Before: train on whole reasoning paths (imitation only), which doesn’t sharply teach the retrieve-vs-parametric judgment. Now: construct preference pairs per sub-query — for each sub-query, which choice (retrieve / don’t) led to the cheaper correct path? — and fine-tune with a DPO-style objective so the model’s retrieval instinct gets calibrated to its actual knowledge boundary.
The honest read: the MDP framing and tree-search-as-data-synthesis are the real novelty. “Atomic decisions” and “retrieval narrative” are nicely-named but are the natural pieces that fall out of the MDP. The two-stage train (SFT then DPO) is a now-standard recipe applied cleverly to a new target (the retrieve decision).
How It Works (Technically)
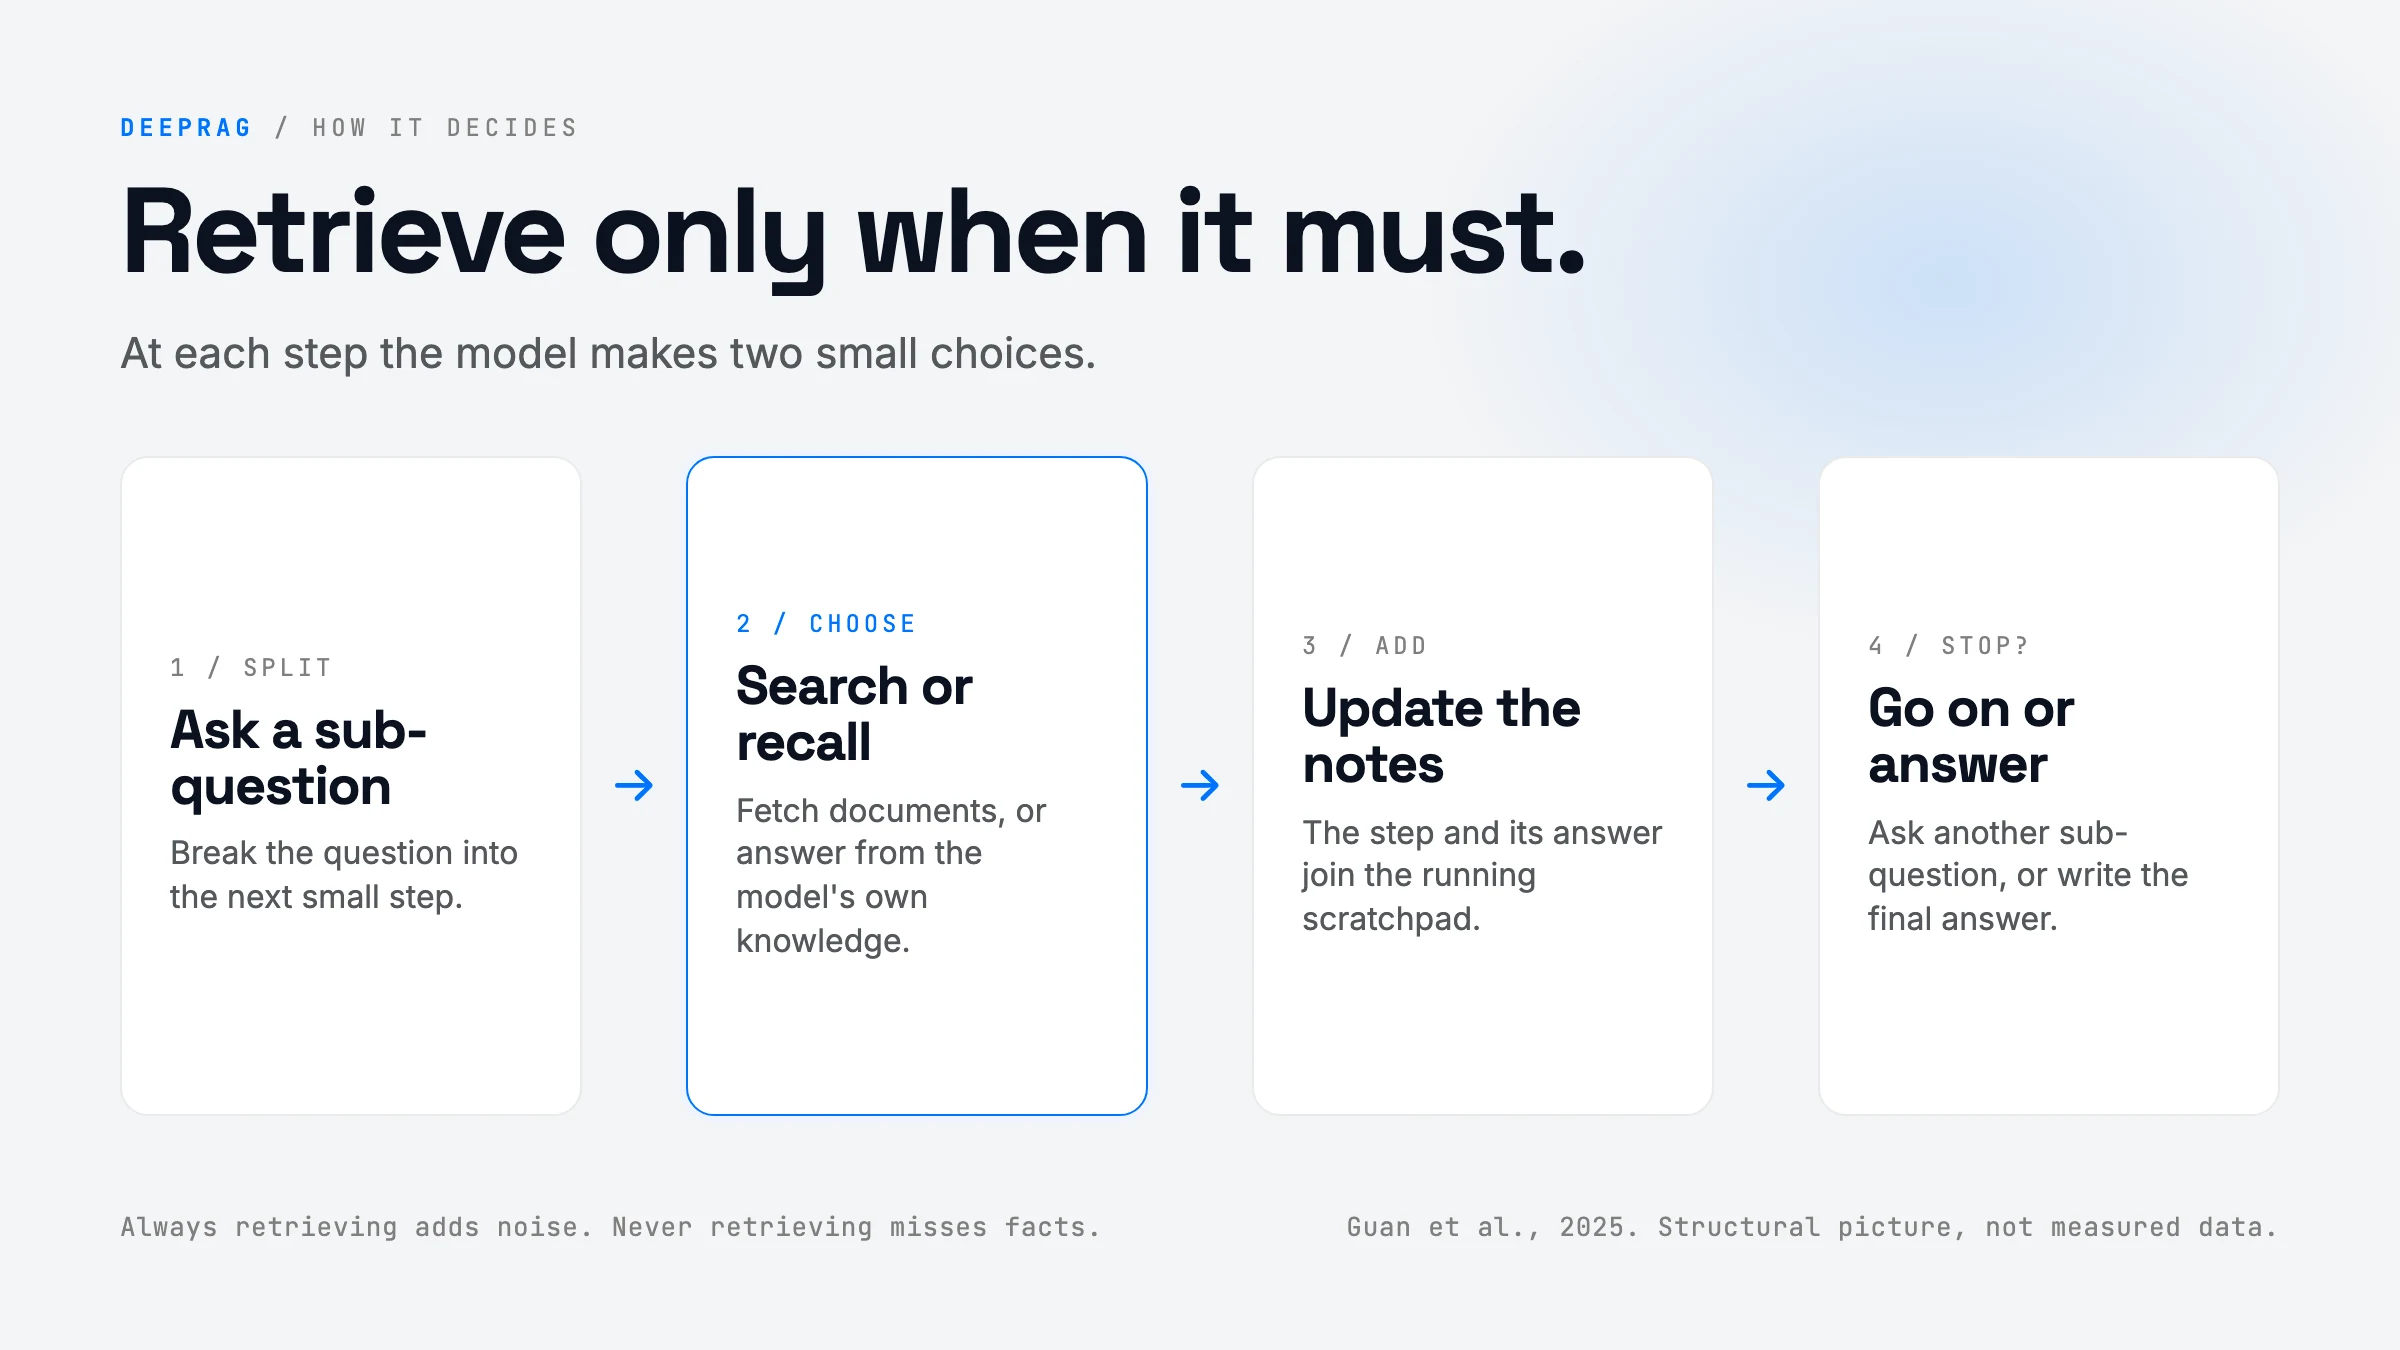
DeepRAG has three machines: an MDP definition, a binary tree search that uses it to mine training data, and a two-stage training (imitation learning + chain of calibration) that turns that data into a model. Let’s demystify each.
The MDP, in plain English
A Markov Decision Process is just: states, actions you can take in a state, how the world changes (transitions), and how much reward you get. Here’s the mapping, with the math translated:
-
State
s_t = (x, (q_1, r_1), ..., (q_t, r_t))— the original questionxplus everything you’ve figured out so far: sub-query 1 and its answer/docsr_1, sub-query 2 and its resultr_2, and so on. Think of it as the running scratchpad. -
Action
a_{t+1} = (σ_{t+1}, δ_{t+1})— two binary decisions bundled together:σ(termination): continue (generate another sub-query) or terminate (write the final answer).δ(atomic decision): for the next sub-query, retrieve external docs or use parametric (in-weights) knowledge.
-
Transition — mechanical bookkeeping. If you terminate, you emit final answer
oand you’re done. If you continue and choseretrieve, you fetch documentsd_{t+1}, generate an intermediate answeria_{t+1}, and append[d_{t+1}, ia_{t+1}]to the scratchpad. If you choseparametric, you just append the intermediate answer. State grows by one step. -
Reward — this is the clever bit. The equation:
R(s_terminal) = −C(o) × T(s_t)Translate it:
C(o)is correctness — it’s1if the final answer is right, and∞if it’s wrong.T(s_t)is the total number of retrievals used. The product is negated. So:- Wrong answer →
C(o)=∞→ reward= −∞. Catastrophic. Correctness dominates everything. - Right answer → reward
= −(number of retrievals). Among correct paths, fewer retrievals = higher (less negative) reward.
In one sentence: be right first; among the right answers, be the cheapest. That single reward is the soul of the paper — it’s why DeepRAG learns to retrieve only when it must.
- Wrong answer →
Architecture & data flow
flowchart TB
  subgraph OFFLINE["OFFLINE: build training data (run once)"]
    Q[Labeled QA pair: question x, gold answer y] --> BTS[Binary Tree Search<br/>Algorithm 1: priority queue by retrieval count]
    BTS -->|cheapest correct trajectory| SFT_DATA[(Stage I data:<br/>subquery → atomic decision → answer)]
    BTS2[Re-run search with Stage-I model] -->|per-subquery: which choice was cheaper-correct?| PREF[(Stage II data:<br/>preference pairs)]
  end
  subgraph TRAIN["TRAINING"]
    SFT_DATA --> IL[Stage I: Imitation Learning<br/>masked SFT on trajectories]
    IL --> M1[Model v1]
    M1 --> BTS2
    PREF --> CC[Stage II: Chain of Calibration<br/>DPO-style preference tuning]
    CC --> M2[Calibrated DeepRAG model]
  end
  subgraph INFER["INFERENCE: cheap greedy decode, no search"]
    UQ[User question] --> M2
    M2 --> LOOP{terminate?}
    LOOP -->|no| AD{retrieve or parametric?}
    AD -->|retrieve| R[Retriever / vector DB] --> IA[intermediate answer] --> LOOP
    AD -->|parametric| IA2[answer from weights] --> LOOP
    LOOP -->|yes| FA[Final answer]
  end
Schematic of the binary tree search. Each sub-query branches into a "parametric" (answer from weights, cost +0) and a "retrieve" (fetch docs, cost +1) node. The search uses a priority queue ordered by retrieval count, so it finds the *cheapest* path that still reaches the correct answer. Click nodes to expand the tree and watch the priority queue prefer low-cost branches.
Binary Tree Search — mining the cheapest correct path
This is Algorithm 1, and it’s the engine that produces training data. Given a question x and its known gold answer y:
- Start a priority queue holding partial trajectories, ordered by retrieval count (cheapest first).
- Pop the cheapest trajectory. Ask the model to generate the next sub-query
q. - If the model signals it’s ready to answer (or you hit max depth), generate the final answer and check
IsEqual(o, y). If correct → return this trajectory (it’s guaranteed cheapest because of the priority ordering). - Otherwise, branch into two children for this sub-query:
- Parametric node: answer
qfrom the model’s own knowledge → enqueue with the same retrieval count. - Retrieve node: call retriever
R(q), answer with the docs → enqueue with retrieval count+1.
- Parametric node: answer
- Loop until you find a correct path or exhaust options (then discard the example).
Because the queue always expands the lowest-cost branch first, the first correct trajectory it returns is the minimum-retrieval correct path — exactly the highest-reward path under the MDP reward. This is a best-first search over the retrieve/don’t-retrieve tree. No RL rollouts, no value network — just search against a ground-truth checker.
The algorithm, simplified
import heapq

def binary_tree_search(x, gold, model, retriever, max_depth):
    # Returns the cheapest correct reasoning trajectory, or None.
    # Each PQ item: (retrieval_count, trajectory_history)
    pq = [(0, [x])]                       # start: zero retrievals, just the question

    while pq:
        r_count, h = heapq.heappop(pq)    # always expand the CHEAPEST path first
        q = model.gen_subquery(h)         # propose the next atomic sub-question

        if model.should_answer(q) or len(h) > max_depth:
            o = model.final_answer(h, q)
            if is_equal(o, gold):         # checked against the known label
                return h                  # first correct == cheapest correct
            continue                      # dead end, drop it

        # Branch 1: answer from the model's own weights  -> cost stays the same
        a_param = model.answer_parametric(h, q)
        heapq.heappush(pq, (r_count, h + [(q, a_param)]))

        # Branch 2: retrieve docs, then answer  -> cost + 1 (retrieval is what we penalize)
        d = retriever(q)
        a_ret = model.answer_with_docs(h, q, d)
        heapq.heappush(pq, (r_count + 1, h + [(q, (d, a_ret))]))

    return None
That ~25 lines is the data-generation contribution. Everything downstream is “train a model to imitate h, then sharpen its branch choices.”
Stage I — Imitation Learning
Take the cheapest-correct trajectories from the search and do supervised fine-tuning on them, so the model learns the format “sub-query → atomic decision → intermediate answer → … → final answer.” One important detail: a masked loss over the retrieved documents — the loss does not train the model to reproduce the document text (that would teach it to memorize noisy passages). It only trains the model’s own tokens (the sub-queries, decisions, and answers). Result: a “Model v1” that decomposes questions and follows the retrieve-or-not pattern reasonably, but whose atomic decisions aren’t yet sharply calibrated.
Stage II — Chain of Calibration
Now sharpen the one thing imitation doesn’t nail: knowing your own knowledge boundary. Re-run the binary tree search using Model v1 to find the optimal (cheapest-correct) path again. Along that path, every sub-query has a known best choice — parametric or retrieve. Build preference pairs per sub-query: for sub-query i, the answer that came from the better choice is “preferred,” the other is “dispreferred.”
Concretely each sub-query has two candidate continuations: r_i¹ = a¹_i (parametric answer) and r_i² = (d_i, a²_i) (retrieved answer). Tag the cheaper-correct one as preferred and train with a preference objective (this is DPO — Direct Preference Optimization — in spirit: push up the log-prob of the preferred continuation relative to the dispreferred one, no reward model needed). For a sub-query where the model genuinely knows the answer, the parametric branch is preferred → the model learns “don’t bother retrieving here.” For one it doesn’t know, retrieval is preferred → “retrieve here.” Repeated across thousands of sub-queries, the model’s retrieve/don’t reflex becomes correlated with its true knowledge — which is the paper’s measured “calibration” win.
The reason this is called a “chain” of calibration: it calibrates every link (sub-query) in the reasoning chain independently, rather than rewarding/penalizing the whole trajectory as one blob.
Built on Prior Work
| Prior idea | What it gave | What DeepRAG changes |
|---|---|---|
| Iterative RAG (IterDRAG, Yue 2024) | Retrieve repeatedly as info needs emerge | Adds learned atomic decisions — don’t retrieve when parametric knowledge suffices |
| Adaptive RAG classifiers/confidence (UAR, FLARE, DRAGIN) | Decide when to retrieve via head/threshold | Drops extra params & fragile thresholds; trains the LLM’s own generation to make the call |
| Self-RAG / Auto-RAG (Asai 2023, Yu 2024) | LLM emits retrieval/critique tokens via data synthesis | Targets the knowledge boundary directly with preference calibration, not just self-reflection |
| Tree-search RAG (AirRAG, MCTS + self-consistency) | Search reasoning paths for better answers | Moves the search offline (data synthesis) so inference stays cheap |
| DPO (Rafailov 2023) | Preference tuning without a reward model | Applies it per-sub-query to the retrieve-vs-parametric decision specifically |
| MDP / RL framing (Sutton & Barto) | States/actions/reward formalism | Reward = −correctness_penalty × retrieval_count, encoding the efficiency tradeoff |
Results & Evidence
What was tested: six open-domain QA datasets. In-distribution: HotpotQA, 2WikiMultihopQA (also the training sources). Out-of-distribution: PopQA, WebQuestions, MuSiQue, and CAG (time-sensitive subset). Backbones: Llama-3-8B-Instruct, Qwen-2.5-7B, Qwen-2.5-32B. Retriever: BM25 over a Wikipedia dump. Metrics: Exact Match (EM) and F1.
Headline numbers:
- +21.99% accuracy on average over baselines (the abstract’s “26.4%” is the relative improvement framing). Consistent wins across backbones and across in/out-of-distribution.
- Lower retrieval cost simultaneously — the whole point. The reward design pays off.
- Calibration is real: an analysis shows DeepRAG’s retrieve-or-not decisions correlate more strongly with whether the model actually possesses the knowledge than baselines do.
Ablations worth knowing:
- Inference extremes: “parametric only” (never retrieve) → poor accuracy. “retrieve only” (always retrieve) → higher accuracy but expensive and still beaten by DeepRAG — confirming that always-retrieving actively hurts on some queries (noise injection).
- Chain of Calibration design: preferences from optimal-path nodes beat (a) building pairs for all nodes and (b) sentence-level partial-order pairs. The sentence-level variant “learned incorrect preferences,” over-relying on internal knowledge → cheap but wrong. So how you build preference pairs matters a lot.
Caveats / what the evidence does NOT establish:
- Training data is synthesized using Exact Match correctness as the oracle. EM is brittle — it rewards string-matching the gold answer, so this works for short-factoid multi-hop QA and may not transfer to long-form, multi-turn, or open-ended generation (the authors flag this in Limitations).
- Retriever is BM25 (lexical), not a strong dense retriever. Results could shift with a better retriever.
- No tools / knowledge graphs — the “knowledge sources” are flat document retrieval. The atomic decision is binary (retrieve vs. not), not “which of N tools.”
- The two training datasets are both multi-hop Wikipedia QA; “out-of-distribution” is still mostly factoid Wikipedia-style QA. Genuinely different domains (code, math proofs, enterprise docs) are untested.
How You’d Use It
If you ship or run any RAG product, DeepRAG is a cost-and-quality lever, not just a research idea. Concrete slots:
-
Your applications: RAG assistants that retrieve too much. If you’re paying per vector-DB query, per reranker call, or per token of injected context, an adaptive retrieve-or-not policy directly cuts inference cost while improving answer quality. That’s a rare both-ways win worth putting on your roadmap.
-
Your harness: multi-hop / agentic answer engines. This is essentially a disciplined ReAct loop where the “should I call the search tool?” decision is learned rather than prompt-coaxed. If you’ve already built agent orchestration, DeepRAG is the per-step gating policy for the retrieval tool — generalizable to “should I call any tool right now, or do I already know this?”
-
Your applications: latency-sensitive deployments. Each skipped retrieval is one fewer network round-trip. For voice or real-time agents, dropping unnecessary retrievals is a UX win, not just a cost win.
-
Your business: a genuinely differentiated capability. A model that knows what it doesn’t know and only reaches for the corpus when needed means fewer “the documents say X” hallucinations from noisy retrieval — a real quality edge to build toward, not a marketing line.
The realistic effort: this is a fine-tuning play, not a prompt trick. You need labeled QA data for your domain, a retriever, and the compute to run SFT + DPO on a 7B-32B model. Several days to a couple weeks of work for someone comfortable with TRL/Axolotl. If you can’t fine-tune yet, you can approximate the behavior (not the calibration) with a prompted decompose-and-decide loop — cheaper, weaker.
Build Your Own (Minimal Recipe)
Smallest version that captures ~80% of the value:
Components
- A base instruct model you can fine-tune (Qwen-2.5-7B or Llama-3-8B).
- A retriever (BM25 via
rank_bm25, or a dense one viasentence-transformers+ FAISS). - A labeled QA dataset with gold short answers (start with HotpotQA — it’s right there).
- A correctness checker (EM is fine to start: normalize + string match).
- Fine-tuning stack:
trl(has bothSFTTrainerandDPOTrainer) +peft(LoRA to keep it cheap).
Build order
- Implement the binary tree search (the pseudocode above). This is the heart — get it producing cheapest-correct trajectories on a few hundred examples first.
- Format the trajectories into the “Follow up: / Intermediate answer: / So the final answer is:” template. Mask the retrieved-doc tokens out of the loss.
- Stage I SFT with LoRA. Verify the model now decomposes and follows the retrieve-or-not format.
- Re-run the search with the Stage-I model to build per-sub-query preference pairs (preferred = cheaper-correct branch).
- Stage II DPO on those pairs. Evaluate EM/F1 and retrieval count vs. an always-retrieve baseline.
The 1-2 genuinely hard parts
- The correctness oracle. EM is noisy; many correct paraphrases get marked wrong, starving your tree search of positive trajectories. Budget time for answer normalization or an LLM-judge fallback.
- Preference-pair construction. The ablation shows getting this wrong (e.g., sentence-level partial orders) teaches the opposite lesson — over-reliance on internal knowledge. Build pairs strictly from optimal-path nodes.
How to Improve It
Five testable directions, roughly in order of payoff:
-
Replace EM with an LLM-judge or semantic-match oracle. This directly fixes the biggest weakness (training signal quality) and should unlock long-form and open-ended QA. Cheap to test: swap the
is_equalchecker and re-run on a long-form set. -
Generalize the binary atomic decision to N-ary tool selection. Instead of {retrieve, parametric}, make it {parametric, web-search, vector-DB, SQL, calculator, KG-lookup}. The tree becomes N-ary; the reward generalizes to per-tool cost. This is the obvious bridge to agentic tool-use and the authors’ own stated future work.
-
Make the reward cost-aware, not just count-aware. Right now
T(s_t)counts retrievals equally. Weight by actual cost (latency, $, token budget) so the policy optimizes a real economic objective — important for production. -
Add a dense/hybrid retriever and a reranker, and re-measure. BM25 is a weak floor; a stronger retriever changes the value of retrieving, which may shift the learned decision boundary. Quantify how much the gains depend on retriever quality.
-
Replace offline tree-search-then-DPO with online RL (GRPO/PPO). The offline scheme can’t discover trajectories the Stage-I model never proposes. An online policy-gradient method with the same
−correctness × costreward could explore better — at the cost of training stability and compute. Worth a head-to-head.
Glossary
- RAG (Retrieval-Augmented Generation) — feeding an LLM relevant retrieved documents at inference so it answers from sources instead of (only) memory.
- Parametric knowledge — facts baked into the model’s weights during pretraining; “what the model already knows” without looking anything up.
- Knowledge boundary — the line between what a model reliably knows and what it doesn’t; models are bad at perceiving their own.
- MDP (Markov Decision Process) — a formalism of states, actions, transitions, and rewards used to model sequential decision-making; the backbone of RL.
- Atomic decision — DeepRAG’s per-sub-query binary choice: retrieve external docs vs. answer from parametric knowledge.
- Retrieval narrative — DeepRAG’s structured chain of sub-queries, each generated from prior results.
- Reward function — the score the MDP optimizes; here
−correctness_penalty × retrieval_count(be right, then be cheap). - Imitation learning — supervised fine-tuning on demonstrated good trajectories (here, the cheapest-correct paths from tree search).
- DPO (Direct Preference Optimization) — fine-tuning on preferred-vs-dispreferred output pairs without training a separate reward model; the mechanism behind Chain of Calibration.
- Preference pair — a (preferred, dispreferred) pair of outputs used as the training signal in DPO.
- Masked loss — computing training loss on only some tokens; here the retrieved-document tokens are masked out so the model doesn’t memorize noisy passages.
- Best-first / priority-queue search — expanding the lowest-cost candidate first; guarantees the first solution found is the cheapest.
- Exact Match (EM) — a metric scoring an answer correct only if its normalized string equals the gold answer.
- Multi-hop QA — questions requiring chaining several facts (find titles → find runtimes → sum).