 BlackArc
as a cheap, decaying preference graph (single-digit edge weights) updated by a Hebbian “fires together, wires together” rule, so per-user memory costs ~25 tokens flat, zero write-time LLM calls, and forgets stale tastes that an all-time counter can’t.
TL;DR
LLM-agent memory systems (Mem0, HippoRAG, etc.) call an LLM on every interaction to extract and reconcile facts — expensive at scale, and a place for the model to hallucinate. FERNme throws that out for agents that serve many people: each user is a sparse node in a per-surface “preference graph,” and edges (strength 0–9) are updated by a no-LLM Hebbian co-occurrence rule, faded by decay, and read back by spreading activation instead of vector search. The result compiles to a token-minimal “card” (~25 tokens) that stays flat as a profile grows, while a full-history baseline balloons 77×. It ties a plain frequency counter on stationary tastes but crushes it when tastes drift (0.72 vs. 0.13 precision@5) or depend on context, and lifts simulated storefront conversion +16%. The honest catch: the authors openly admit none of the mechanisms are new and they never ran the head-to-head against a real LLM memory — so this is a strong cost/robustness story, not yet a proven answer-quality win.
Problem & Motivation
Agents are shifting from chatting to acting — buying, booking, re-ordering, routing — and doing it across a website, a desktop app, and a phone. To be useful across visits they need memory. But the dominant memory designs were built for a different problem and carry three properties that hurt once an agent acts on behalf of many users:
- Writes invoke an LLM every interaction. Mem0-style memory extracts and reconciles facts with a model call (≈2 calls per interaction). At scale that’s real money, real latency, and a write-time hallucination surface — the memory itself can be wrong.
- They’re graded on question-answering, not actions. A high QA recall score doesn’t tell you whether the agent did the right thing (completed the purchase, re-ordered the right item).
- They assume one user, one deployment. No notion of per-tenant isolation, consent, or who owns the personal data.
Concrete pain: you’re running an agent for 100,000 shoppers. Every message they send triggers a couple of GPT calls just to update memory — before the agent does any actual work — and the profile you’ve built grows without bound, so the prompt you carry gets bigger and pricier every visit. FERNme’s premise: for a memory that sits behind an agent acting for many people, the priorities invert — writes must be near-free, success is an outcome, and isolation/consent are first-class.
What’s New (Core Contribution)
The author is unusually candid: the mechanism family (Hebbian learning, ACT-R decay, spreading activation, fuzzy sets) is decades-old cognitive science and several recent systems use it. The contribution is the combination and framing, not the parts.
- A memory write with no per-interaction LLM call. Before: extract+reconcile via an LLM every turn. Now: a deterministic map from a structured event to “active attributes” via a catalog/vocabulary table, then a saturating Hebbian weight bump. Zero model calls on the hot path.
- Differential, population-prior encoding as a token mechanism. Before: store each user’s full profile. Now: keep a shared “average user” prior (privacy-protected) and store only where a user deviates from it — so the per-user card stays tiny and new users get a warm start.
- Action-coupled, outcome-oriented framing. Before: benchmark on QA recall. Now: memory drives tool defaults, ranking, and proactive triggers, and is evaluated by conversion lift, not just recall.
- Multi-tenant, user-owned design. Before: single-user, single-deployment. Now: per-(surface, user) isolation, consent-gated reads/writes, a glass-box card the user can edit/export/delete, an HMAC audit chain, and an opt-in cross-surface “supernode” the user owns (default-deny sharing).
How It Works (Technically)
The core move: treat a user not as a paragraph of remembered facts, but as a set of weighted edges to attributes, and update those weights with arithmetic instead of a language model.
1. Substrate — the graph. Each user is a node. It connects to attribute nodes like
pref:organic or !pref:upsells (the ! is an explicit negative preference) by an edge carrying
a continuous strength in [0, 9] — a “fuzzy” single-digit membership. Storage is sparse: you only
store an edge when the user deviates from the population average; otherwise reads fall through to the
shared prior. A separate association graph holds attribute↔attribute co-occurrence weights.
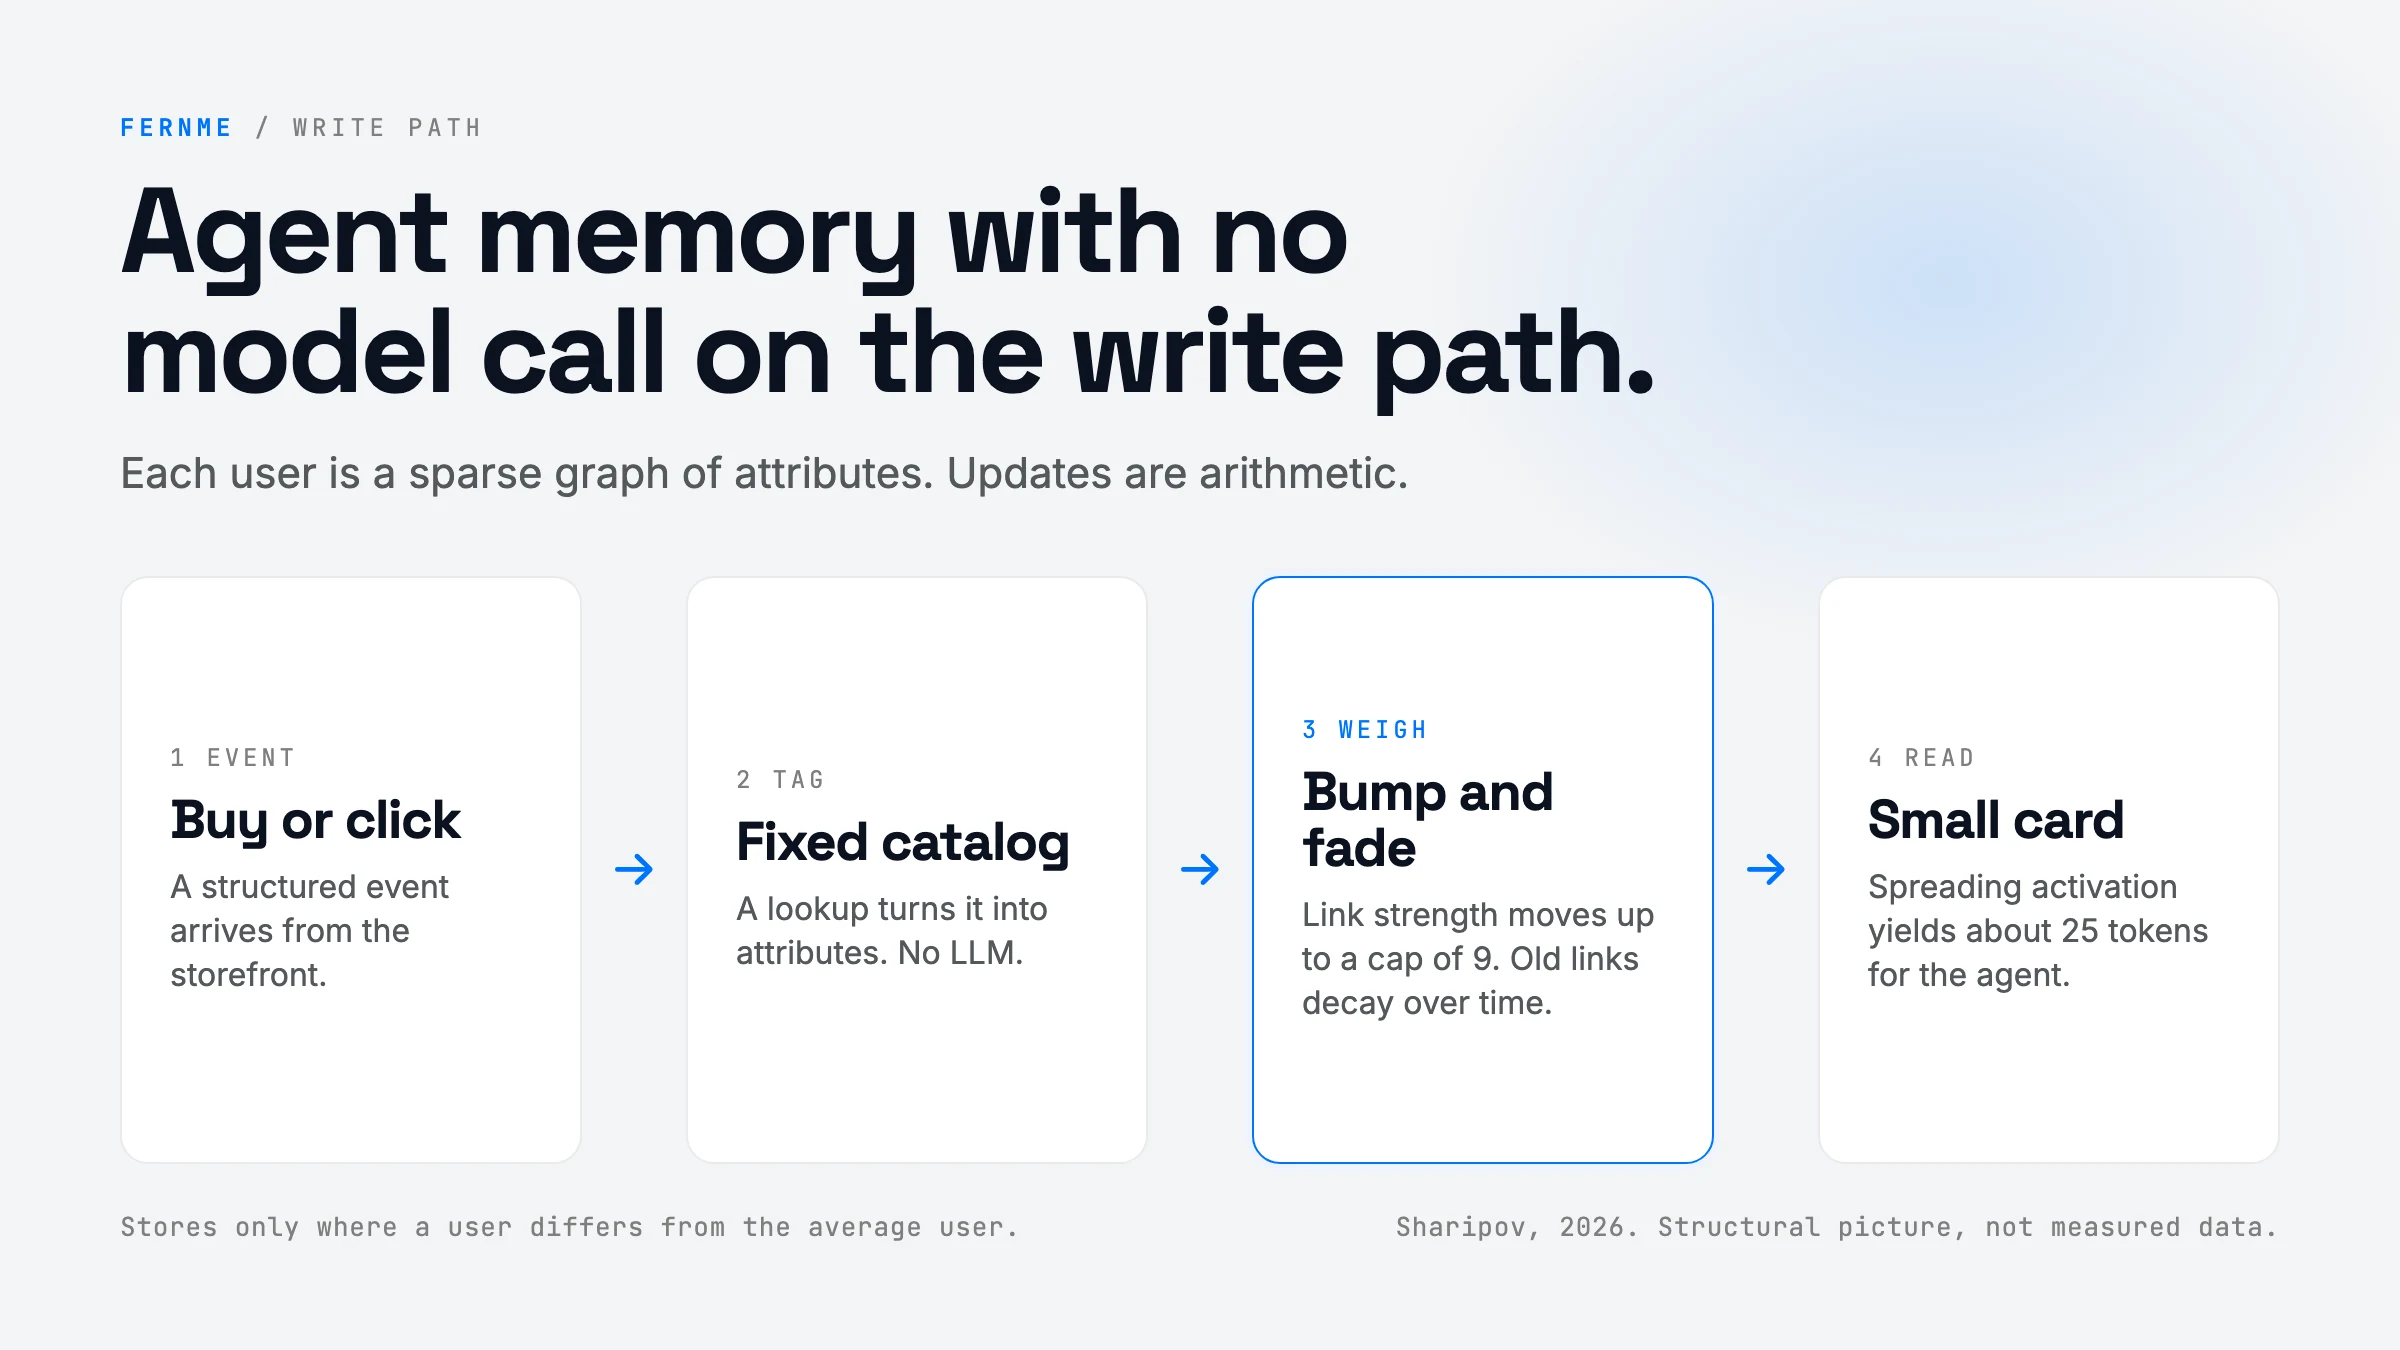
2. Write rule (the heart — no LLM). An incoming event (a purchase, a click, a return) is mapped by a deterministic function to its active attributes using a controlled vocabulary / catalog table. No model call. For each active attribute, the weight is nudged:
w ← w + α · m · (1 − w/9)In plain English: move the weight up by a learning-rate α times the event magnitude m, but
scale the step by how far you are from the ceiling of 9 (1 − w/9). So a brand-new preference
shoots up fast, and a near-maxed one barely moves — the weight saturates at 9 instead of running
away. (This is the classic “logistic-ish” approach to a bounded counter.)
Three more pieces hang off the write:
- Hebb on pairs. Attributes that fire together in the same event strengthen their edge in the association graph — “what goes with what.” This is what later powers context-aware retrieval.
- Negative edges. A decline or a return writes a negative attribute (
!pref:...) as a first-class signal — you remember what someone doesn’t want, not just what they do. - Confidence. Separately tracked as
confidence = 1 − e^(−γ · hits)— it rises toward 1 as an attribute recurs across events. Crucially, confidence is decoupled from weight: weight says “how strong,” confidence says “how sure,” and the agent only acts silently on high-confidence edges.
3. Forgetting (what makes it adaptive). A periodic batch decay fades unreinforced edges:
w ← w · e^(−λ · Δt)Each edge’s strength multiplies by an exponential of elapsed time Δt and a decay rate λ — so
anything you stop reinforcing shrinks, and once it drops below a floor it’s dropped entirely. This
is exactly why FERNme beats a frequency counter under drift: an all-time counter can never forget
last year’s favorite, but FERNme’s decay lets a new favorite overtake an old one (in their data,
afternoon tea shifts jasmine 3.25 → earl-grey 5.84). An optional per-edge salience s ∈ [0,1]
can slow decay for behaviorally significant one-off signals (λ_eff = λ(1 − βs)), off by default.
4. Differential / population-prior encoding (what makes it cheap). The per-surface prior is the running mean of all users’ weights, protected by k-anonymity and Laplace differential privacy. You store a user’s edge only when it deviates past a threshold; everything else reads through to the prior. A brand-new user is cold-started with guessed edges synthesized from the prior, IDF-weighted so rare-but-distinctive attributes (which carry more signal) earn the slots. The user’s own edges always outrank guesses, and a guess relearns from scratch the moment real evidence arrives.
5. Retrieval — spreading activation, not vector search. To build the prompt, FERNme doesn’t embed-and-rank. It lights up the user node plus any context seeds (e.g. “it’s afternoon,” “user is in the tea aisle”) and lets activation flow over the weighted edges, using ACT-R base-level activation (recency × frequency), lateral inhibition inside mutually-exclusive clusters (so “likes coffee” suppresses “likes tea” rather than both firing), and temporal decay. The top-N activated edges compile into the card — and each is tagged with a two-color mark: known (act silently) vs. guessed (verify before acting).
6. Action coupling & governance. The card drives tool defaults, result ranking, and proactive triggers (due-to-reorder, fading-favorite), all gated by uncertainty. Every event payload is treated as untrusted and sanitized (allowlist, size caps, injection-pattern dropping) before it can become memory, and every action is logged to a tamper-evident HMAC chain.
Trace one event through: A logged-in shopper buys organic oat milk in the morning.
→ Event mapped (no LLM) to active attributes {pref:organic, pref:oat-milk, ctx:morning}.
→ Weights bumped via the saturating rule; organic edge goes 4.0 → 4.6; the pair
(oat-milk, morning) strengthens in the association graph; confidence on oat-milk ticks up.
→ Decay later fades a tea preference she hasn’t touched in weeks.
→ Next visit, retrieval seeds the user node + ctx:morning, activation flows, and the card surfaces
“organic, oat-milk, likely re-order soon” in ~25 tokens — no model call was made to remember any of it.
Architecture & data flow
flowchart LR
  EV[Event: buy / click / return] --> MAP[Deterministic tag mapper<br/>catalog + controlled vocab<br/>NO LLM]
  MAP --> WR[Hebbian write<br/>w ← w + α·m·1−w/9]
  WR --> G[(Per-surface preference graph<br/>user node — attribute nodes<br/>+ association graph)]
  PRIOR[(Population prior<br/>k-anon + DP)] -. store only deviations .-> G
  G --> DECAY[Batch decay<br/>w ← w·e^−λΔt]
  DECAY --> G
  G --> RET[Spreading activation<br/>+ context seeds]
  RET --> CARD[Token-minimal card<br/>~25 tokens, known/guessed marks]
  CARD --> ACT[Agent action layer<br/>defaults · ranking · triggers<br/>uncertainty-gated]
Schematic of the preference graph you can orbit: the central user node links to
attribute nodes; edge thickness = weight (0–9), green = liked, red = a negative !pref edge.
This is the whole "memory" for one user — no embeddings, no stored transcript.
The two equations that are the paper. Top: the saturating Hebbian write — each reinforcement moves fast early, then asymptotes at 9. Bottom: decay lets a new favorite (earl grey) overtake a fading one (jasmine) — the drift case an all-time counter fails. Drag the sliders for α and λ.
The algorithm, simplified
# One user = a dict of attribute -> edge weight in [0, 9]. No LLM anywhere on this path.
CEIL = 9.0

def write(user, event, assoc, alpha=0.6, gamma=0.4):
    attrs = map_event_to_attrs(event)          # deterministic catalog lookup, NOT an LLM call
    for a in attrs:                            # a like "pref:organic" or "!pref:upsells"
        w = user.weight.get(a, prior(a))       # unseen edges fall through to the population prior
        m = event.magnitude                    # e.g. 1.0 buy, 0.3 click, -1.0 return
        user.weight[a] = w + alpha * m * (1 - w / CEIL)   # saturating bump, caps at 9
        user.hits[a] += 1
        user.conf[a] = 1 - math.exp(-gamma * user.hits[a])  # "how sure", separate from weight
    for a, b in itertools.combinations(attrs, 2):
        assoc[(a, b)] += 1                     # Hebb: things seen together wire together

def decay(user, dt, lam=0.05, floor=0.2):
    for a, w in list(user.weight.items()):
        w *= math.exp(-lam * dt)               # unreinforced edges fade -> enables forgetting/drift
        if w < floor: del user.weight[a]       # drop it; keeps the card small regardless of tenure
        else:         user.weight[a] = w

def retrieve(user, assoc, context_seeds, top_n=8):
    act = {a: base_level(user, a) for a in user.weight}      # ACT-R recency x frequency
    for seed in context_seeds:                               # light up context, let it spread
        for a in user.weight:
            act[a] += assoc.get((seed, a), 0) * user.weight[a]
    top = sorted(act, key=act.get, reverse=True)[:top_n]
    return [(a, "known" if user.conf[a] > 0.7 else "guessed") for a in top]  # the card
Built on Prior Work
The paper is explicit that it claims none of these mechanisms — it claims the system around them.
| Prior idea | What it gave | What FERNme changes |
|---|---|---|
| HippoRAG / HippoRAG 2 | Associative retrieval over a knowledge graph via Personalized PageRank | Same retrieval family, but for who the agent serves (personalization), not document retrieval; no LLM-based indexing |
| Mem0 (production memory) | Rich LLM extraction + reconciliation per write; vector retrieval | Trades nuance for near-zero write cost; makes the trade-off explicit (optional gated/offline LLM modes) |
| HeLa-Mem / Ori-Mnemos | Hebbian + ACT-R decay + spreading activation for a single agent/user | Recasts it as multi-tenant, user-owned, with a private collective prior |
| MemGPT/Letta, Zep/Graphiti | Tiered context paging; temporal validity graphs | Tiers (Card/Cabinet/defaults) exist to bound tokens for a live action loop; handles time via decay, not a temporal graph |
| ACT-R, Hebb, Collins–Loftus, Zadeh | Activation decay, “fire together wire together,” spreading activation, fuzzy sets | Used verbatim as the engine — credited, not claimed |
Results & Evidence
The good (simulation + one natural dataset):
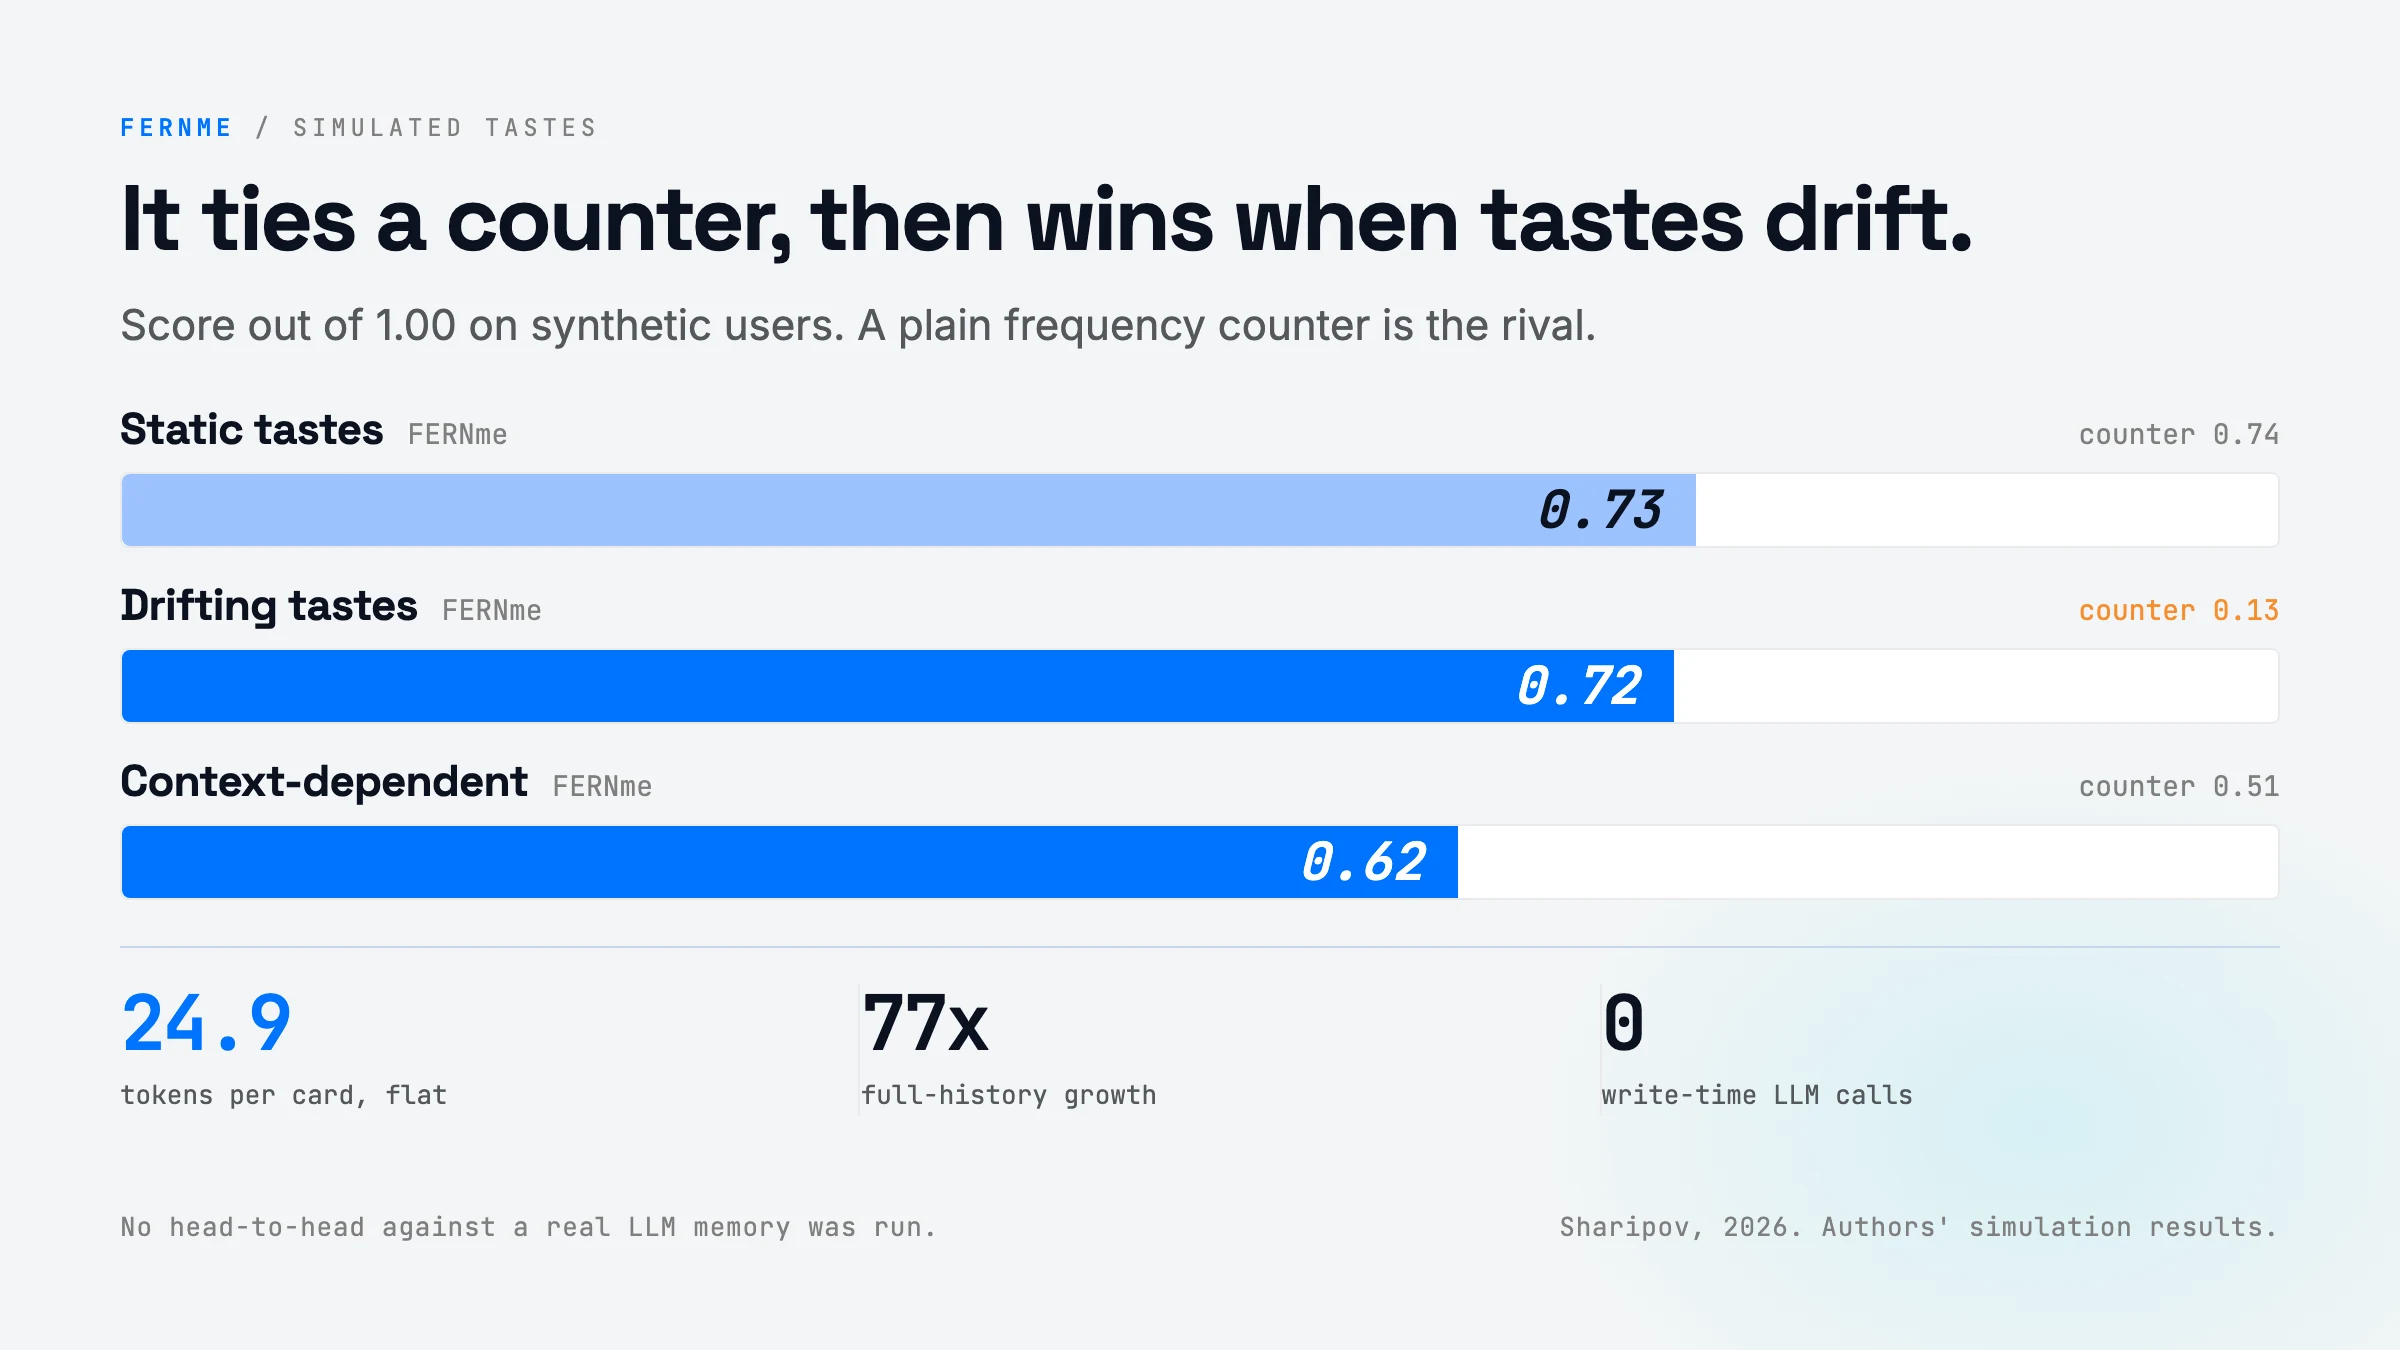
- Flat, free writes. Card holds 24.9 ± 0.5 tokens, essentially flat (+0.001 tokens/interaction) while a full-history baseline grows to 77× by 120 interactions. 0 write-time LLM calls vs. ~2/interaction for extraction memory.
- Robustness where counters fail. Static recall: 0.73 vs. 0.74 (ties frequency — no win). Drift: 0.72 vs. 0.13. Context: 0.62 vs. 0.51. It’s the only method strong across all three.
- Outcome metric. Simulated storefront: +16% relative conversion lift over a popularity baseline.
- Natural data (the “Elena” set, 86 free-form diary entries about one fictional person). Ingested all 86 with 0 write-path LLM calls, kept a ~40-token card, retained 16/16 stated permanent facts, handled drift, and used ~10× fewer tokens than extraction and ~240× fewer than full-history. On a LoCoMo-style QA probe at a harsh top-10 budget it answered 36.4% vs. 9.1% (frequency/recency), climbing to 76% @ top-20 and ~91% @ top-30.
The honest caveats (the author states most of these outright):
- No human study. It’s simulation plus one synthetic person; synthetic experiments define their own ground truth, and “Elena” is fictional with agent/parser-driven tag extraction (so fact coverage is high by construction — the QA result probes retrieval, not end-to-end answer quality).
- The decisive experiment was not run. A real Mem0 (LLM) head-to-head is implemented as a harness hook but needs API keys and was not executed — so the cost win is proven, the answer-quality parity with an LLM memory is not. This is the single open question.
- Nuance gap. A co-occurrence counter genuinely misses causal/contextual preferences an LLM extractor would catch (“avoids dairy because lactose-intolerant”).
- Mapping dependency. The no-LLM write only works if the catalog/vocabulary is good; thin-metadata surfaces degrade to coarse attributes.
- Token numbers are estimates (chars/4, tiktoken unavailable offline); spreading-activation parameters are hand-tuned; single-digit weights lose fine degree.
Read it as: a credible, well-instrumented argument that cheap arithmetic memory is the right default for high-volume, action-taking agents — with the marquee comparison still owed.
How You’d Use It
This lands squarely in agentic orchestration territory — memory for any agent you run that serves more than one user.
- Your applications — a personalization layer. Most agents you’d ship (support, shopping, booking, internal copilots) re-derive the user from scratch every session or pay per-turn LLM tax to remember. FERNme is a drop-in memory sidecar: cheap to run per user, flat token cost, and it forgets — so profiles stay current without a cleanup job. The cost math is a real lever: ~$0.0005 to read a card 86 times vs. ~$0.12 to carry full history.
- A trust/compliance property worth having anyway. The user-owned, consent-gated, glass-box-editable, audit-chained design is exactly what you’d want to show a legal or compliance reviewer for your own product. “We can show every user their memory card and let them delete it” is a real feature to build in from the start, not a bolt-on later.
- Your harness — multi-tenant from day one. If you’ve built a multi-agent system, the per-(surface, user) isolation and population prior mean one deployment serves all of your end-users without cross-contamination — and new users get a warm start from the prior instead of a cold one.
- Where it slots in your loop: it replaces the “load user memory” step before the agent acts and the “update memory” step after — turning two LLM calls per turn into two dict updates.
Realistic effort: a usable v1 is a few days (see below); the work is in the catalog/vocabulary and the retrieval tuning, not the algorithm.
Build Your Own (Minimal Recipe)
You can capture ~80% of the value with surprisingly little:
- Define your attribute vocabulary + event→attribute map. This is the real work. A table/function
that turns “bought SKU 12345 at 8am” into
{pref:organic, pref:oat-milk, ctx:morning}. Start hand-written from your own catalog or domain; an offline LLM pass can enrich it later (off the hot path). - Store users as
{attribute: weight}dicts in Postgres/Redis (the repo ships a Postgres backend). Addhitsandconfidenceper edge, and anassoctable for attribute pairs. - Implement the four functions from the snippet above:
write(saturating Hebbian + Hebb pairs + negative edges),decay(batch cron job),retrieve(base-level activation + context seeds), and acard()formatter that emits the top-N as compact text with known/guessed marks. - Add the population prior as a running per-attribute mean; store only deviations; cold-start new users from IDF-weighted prior guesses.
- Gate actions by confidence: act silently on
conf > 0.7, otherwise verify with the user.
The two genuinely hard parts: (a) the event→attribute mapping quality (garbage in, coarse memory out), and (b) tuning the spreading-activation/decay parameters so retrieval feels right — budget a small eval harness with a few drift/context test cases (mirror their Elena setup). Everything else is plumbing. Libraries: just Postgres/Redis + a few dozen lines of Python; no model, no vector DB needed.
How to Improve It
Limitations are leverage — here’s where you could push past the paper:
- Run the missing Mem0 head-to-head. The whole thesis hinges on “cheap memory is good enough.” Wire up the existing harness hook, spend the API keys, and publish the answer-quality vs. cost curve. That single experiment is the highest-value thing anyone could do with this repo.
- Hybrid write: cheap by default, LLM on surprise. Run the no-LLM path always, but trigger an offline LLM extraction only when an event is high-magnitude or low-confidence (uncertainty-gated writes). Recovers most of the nuance gap while keeping average write cost near zero.
- Learn the vocabulary/mapping instead of hand-coding it. The mapping dependency is the real fragility. Periodically mine logs to propose new attributes and merge synonyms — closing the gap on thin-metadata surfaces without touching the hot path.
- Auto-tune decay and activation. The salience and λ parameters are hand-set; fit them per-surface from held-out drift/context outcomes (even a simple grid search on conversion lift would beat hand-tuning).
- Richer than single-digit fuzziness. 0–9 weights throw away degree. Test whether continuous weights or a second “intensity” channel improves context retrieval without bloating the card.
- Cross-surface association transfer. The supernode links surfaces but each has its own association graph; sharing attribute co-occurrence (not personal weights) across surfaces could warm-start context retrieval on a new surface — a privacy-safe collective benefit.
Glossary
- Hebbian update — “neurons that fire together wire together”; here, attributes seen in the same event strengthen their connection, with no LLM involved.
- Spreading activation — retrieval by lighting up a starting node and letting “energy” flow over weighted edges to related nodes, instead of embedding-and-ranking.
- ACT-R base-level activation — a cognitive-science formula scoring a memory by how recently and frequently it’s been used.
- Saturating update — a weight bump scaled by distance to a ceiling, so it rises fast then levels off (here, asymptotes at 9) instead of growing unbounded.
- Decay (λ) — exponential forgetting of unreinforced edges; the reason FERNme can drop a stale favorite where an all-time counter can’t.
- Population prior — the “average user” profile (privacy-protected) that unseen edges read through, giving new users a warm start and shrinking storage to deviations only.
- Differential privacy / k-anonymity — formal guarantees that the shared prior can’t be reverse- engineered to identify or expose any single user.
- IDF weighting — inverse-document-frequency; up-weights rare, distinctive attributes because they carry more signal than common ones.
- The card — the token-minimal text summary (~25 tokens) compiled from the top activated edges and injected into the agent’s prompt; each item marked known (act) or guessed (verify).
- Multi-tenant — one deployment safely serving many isolated users/clients, with no cross-leakage.
- Negative edge (
!pref) — an explicit “doesn’t want this” signal, treated as first-class memory. - LoCoMo — a long-conversation memory QA benchmark format used here as a retrieval probe.